PatentNext Takeaway: Generative artificial intelligence patenting has entered a new phase. According to the World Intellectual Property Organization (WIPO), more GenAI patent families were published during 2024 and 2025 than during the entire preceding decade. GenAI patenting is also expanding beyond traditional technology companies into finance, telecommunications, infrastructure, and other industries. For businesses developing or deploying GenAI, the data reinforces the need for systematic invention harvesting, technically detailed patent drafting, deliberate filing strategies, and ongoing monitoring of an increasingly crowded competitive landscape.

****

WIPO’s Updated Patent Trends Report in GenAI

On July 14, 2026, WIPO announced the publication of its latest Technology SPARK Report, Patent Trends Update in GenAI. The report updates WIPO’s 2024 patent landscape analysis by extending the available patent data through 2025.

The updated report examines a two-year period during which, according to WIPO, GenAI moved from “early-stage experimentation” toward “large-scale commercial deployment” across an expanding range of industries and applications.

That transition is significant. The initial wave of public attention surrounding GenAI focused heavily on consumer-facing tools capable of generating text, images, software code, and other content. The latest patent data indicate that the underlying innovation activity is now moving beyond experimentation and into broader commercial implementation.

WIPO’s announcement characterizes the change as a new milestone: more GenAI patent families were published during 2024 and 2025 than during the entire previous ten-year period.

For companies and patent practitioners, the report provides more than a retrospective measure of filing activity. It is also an indicator of where companies are making substantial research and development investments—and where competitive patent positions may be forming.

Accelerating GenAI Patenting Activity

The most striking finding is the rate at which GenAI patenting has accelerated.

Published GenAI patent families increased from approximately 14,000 in 2023 to more than 37,800 in 2025. More than 56,000 new GenAI patent families were published during 2024 and 2025 combined, exceeding the cumulative number published from 2014 through 2023.

WIPO’s more detailed report similarly describes GenAI patenting as accelerating at an “unprecedented pace.” It reports that the number of published GenAI patent families increased from approximately 14,000 in 2023 to more than 37,000 in 2025 and that the 2024–2025 total exceeded the entire output of the preceding decade.

The Figure below illustrates the development of global GenAI inventions from 2014 through 2025, measured by the number of published patent families according to their earliest publication year.
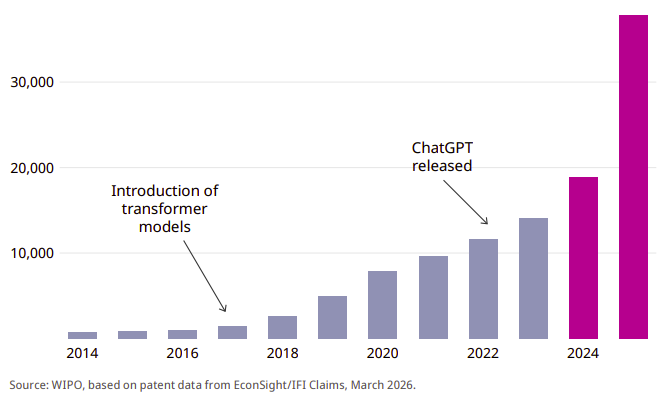
The figure refers to published patent families rather than merely the number of individual national patent publications. A patent family generally groups related patent filings directed to the same or substantially similar invention. Patent-family data can therefore provide a more meaningful measure of distinct inventive activity than a count that treats every national counterpart as a separate invention.

The timing is also important. Patent applications ordinarily are not published immediately after filing. As WIPO explains, the recent increase reflects, at least in part, the closing of the typical approximately 18-month gap between filing and publication following the post-ChatGPT increase in research and development.

Consequently, the patent applications becoming visible today may reflect research and business decisions made well over a year earlier. Current—and still unpublished—filing activity may be even further advanced.

GenAI Is a Growing Share of All AI Patenting Activity

GenAI remains one portion of the broader artificial intelligence patent landscape. Its relative share of AI patenting, however, continues to increase.

According to WIPO:

  • GenAI accounted for approximately 4.2% of AI-related patent-family publications in 2017;
  • that share increased to 6.1% in 2023; and
  • GenAI accounted for approximately 8.7% of all AI patent-family publications in 2025.

The increase indicates that GenAI is not merely growing as part of an overall rise in AI patenting. It is accounting for an increasingly large portion of the broader AI patent landscape.

That distinction matters when companies assess freedom to operate, competitive positioning, and patentability. A technical field experiencing rapid growth can become crowded quickly. Prior-art searches that were reasonably comprehensive only a year or two ago may no longer capture the most relevant patent landscape, particularly as recently filed applications continue to publish.

Patent applicants should therefore avoid treating GenAI as a static technology category. Search strategies, patentability assessments, claim drafting, and competitive analyses may need to be updated throughout product development and prosecution.

Main GenAI Models and Modes

WIPO’s updated data also show that the technological center of gravity within GenAI is changing. The report categorizes GenAI patent families both by the underlying model architecture and by the type—or “mode”—of data the systems process or generate. Viewed together, these categories show a transition from a field once dominated by image-focused generative models toward one increasingly driven by large language models, diffusion models, and multimodal systems with broader commercial applications.

Large Language Models Have Overtaken GANs

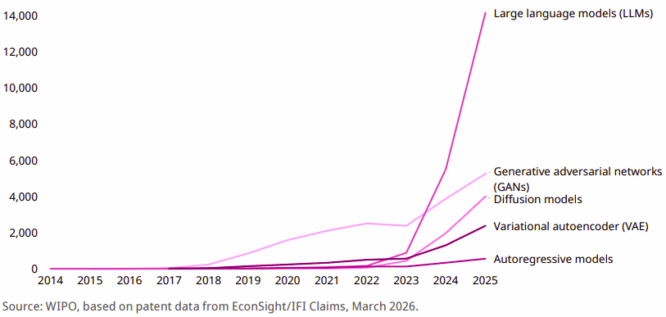
The most significant change among GenAI model types is the rise of large language models (LLMs). From 2014 through 2025, approximately 20,900 patent families were published in the LLM category, compared with approximately 18,800 patent families relating to generative adversarial networks (GANs). The speed of this reversal is notable: in 2023, WIPO identified only 881 LLM patent families, compared with 2,370 GAN patent families. By 2025, however, LLM patent-family publications had increased to more than 14,100—nearly three times the approximately 5,245 GAN patent families published that year.

The Figure below illustrates the development of GenAI inventions across five core model categories—large language models, generative adversarial networks, diffusion models, autoregressive models, and variational autoencoders—measured by the number of published patent families from 2014 through 2025.
The shift from GANs to LLMs reflects the broader technological evolution of GenAI. GANs were the dominant generative architecture for much of the prior decade, particularly in areas such as image synthesis and data augmentation. Transformer-based architectures underlying LLMs, however, have become central to the current GenAI wave, as the commercial adoption of language and multimodal systems has translated into rapidly increasing patent activity. GANs remain relevant for applications such as image enhancement, synthetic-data generation, and real-time inference, but they no longer occupy the leading position in GenAI patenting.

Diffusion models are also becoming an increasingly important part of the patent landscape. WIPO reports that diffusion-model patent families increased from 441 in 2023 to nearly 4,000 in 2025, making diffusion models the third-largest GenAI model category by cumulative patent volume. Variational autoencoders also experienced substantial growth, while the comparatively limited growth of the separate “autoregressive model” category may reflect applicants’ increasing preference for the more specific and commercially recognizable term “large language model.”

Overall, the model data show that GenAI patenting has moved decisively from a GAN-dominated period toward one led by LLMs and, increasingly, diffusion models. According to WIPO, this development mirrors a broader transition from adversarial image generation toward large-scale language and multimodal systems having wider application potential.

Text and Other GenAI Modes Are Catching Up With Image and Video

WIPO separately categorizes GenAI inventions according to the types of input and output data used by the systems. These modes include image and video, text, speech and audio, software and code, 3D image modeling, and biological information such as molecules, genes, and proteins. Because modern GenAI systems can process multiple types of information, a single patent family may be associated with more than one mode.

Image and video remain the largest GenAI mode by cumulative patent volume. WIPO identified approximately 40,000 image- or video-related patent families published between 2014 and 2025, including more than 13,800 in 2025 alone. This category includes inventions involving multiple model types, including GANs, diffusion models, variational autoencoders, and multimodal LLMs. Its continued lead therefore reflects the broad range of architectures capable of processing or generating visual content.

Text-related patenting, however, is rapidly closing the gap. The number of text-related patent families increased from approximately 3,400 in 2023 to nearly 11,800 in 2025. WIPO associates this growth with the rise of LLM-related inventions and the increasingly central role of text generation, processing, and understanding within the GenAI ecosystem.

The Figure below illustrates the development of GenAI inventions across the principal data modes—including image and video, text, speech and audio, software and code, 3D image modeling, and molecules, genes, and proteins—measured by the number of published patent families from 2014 through 2025.
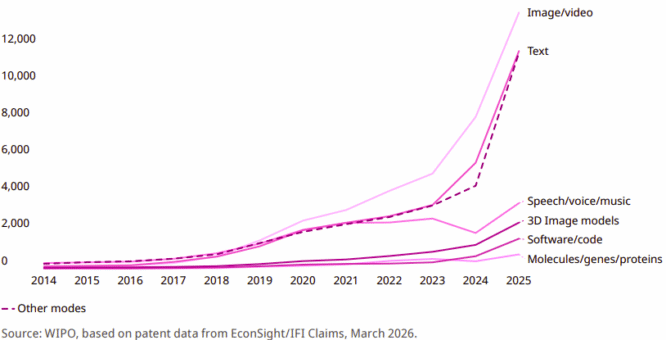
Other modes are also expanding, although from smaller bases. Software- and code-related patent families increased from 339 in 2023 to 1,616 in 2025, reflecting increased patenting activity involving AI-assisted code generation and the integration of GenAI into software-development workflows. Patent families involving 3D image modeling increased from 908 in 2023 to 2,484 in 2025, consistent with growing GenAI applications in virtual environments, gaming, product design, and 3D content creation.

The molecules, genes, and proteins category showed more uneven growth, but WIPO reports that it continues to reflect GenAI’s expanding use in drug discovery, protein design, and other life-sciences applications. Speech, voice, and music patenting also recovered in 2025 after declining during 2024. WIPO suggests that the apparently slower growth of the speech category may partly result from classification practices, because modern audio systems are increasingly implemented through multimodal LLMs and may therefore be classified under text or other modes.

For patent applicants, these trends reinforce the importance of describing both the underlying model architecture and the different data modes that an invention may support. A specification directed only to a single model type or one form of input and output may provide insufficient flexibility as GenAI systems become increasingly multimodal. Where supported by the invention, applications should describe alternative implementations involving text, images, audio, code, and other relevant data types, while also identifying the technical features that distinguish the invention from merely using a conventional GenAI model for an intended result.

From Early-Stage Experimentation to Large-Scale Commercial Deployment

WIPO’s characterization of the field’s transition from experimentation to commercial deployment may be as important as the raw filing numbers.

During an early-stage technology cycle, patent filings often concentrate on foundational models, basic architectures, or proof-of-concept implementations. As commercialization expands, patentable innovation typically becomes more distributed. Inventions may arise not only from the models themselves, but also from the systems used to train, deploy, monitor, secure, validate, and integrate those models.

For GenAI, potentially protectable innovation may occur at multiple layers, including:

  • model architecture and training;
  • data acquisition, preparation, and governance;
  • inference-time processing;
  • model orchestration and routing;
  • retrieval and contextual-data systems;
  • multimodal input and output processing;
  • agent-based workflows;
  • model evaluation and output validation;
  • security, privacy, and access control;
  • human-machine interfaces;
  • integration with enterprise or industrial systems; and
  • application-specific technical improvements.

Not every use of GenAI will produce a patentable invention. Merely applying a known model to a new business objective may face substantial patent-eligibility, novelty, obviousness, or written-description issues. See, e.g., PatentNext: Federal Circuit Rejects AI Claims Lacking Technical Detail (regarding the decision in Recentive Analytics, Inc. v. Fox Corp., No. 2023-2437 (Fed. Cir. Apr. 18, 2025)).  But commercial deployment frequently creates technical implementation problems that did not arise—or were not fully appreciated—during early experimentation.

Those implementation problems may themselves lead to patentable solutions. Companies should therefore conduct invention harvesting not only with core AI researchers, but also with engineering, product, security, infrastructure, data, and industry-domain teams responsible for deploying the technology.

GenAI Patenting Is No Longer Limited to Technology Companies

Another important point from WIPO’s announcement is the expanding range of organizations seeking GenAI patent protection.

WIPO reports that GenAI patents are no longer being filed only by conventional technology companies. Large enterprises in finance, telecommunications, infrastructure, and other digital-service industries are also becoming significant participants. WIPO Director General Daren Tang described content generation as the initial impact of GenAI, while identifying its effect on the innovation process itself as a coming frontier.

This expansion has several implications.

First, companies should not assume that their relevant patent competitors are limited to the most visible AI model developers. A financial institution, telecommunications provider, utility, manufacturer, healthcare company, or logistics business may develop patentable GenAI systems tailored to its particular technical environment.

Second, industry-specific data and operational expertise may become increasingly important sources of differentiation. Many companies will use commercially available foundation models. The protectable innovation may instead lie in how those models are integrated into proprietary systems, constrained by operational requirements, supplied with specialized data, or used to improve a technical process.

Third, GenAI patent strategies may increasingly overlap with established patent portfolios in fields such as networking, cybersecurity, industrial control, medical technology, energy management, communications, and enterprise software. Patent teams may need to coordinate GenAI filings with existing technology-specific portfolios rather than treating “AI patents” as a separate and isolated category.

The Growing Strategic Importance of Intellectual Property in the GenAI Economy

WIPO concludes that the latest data underscore the growing strategic importance of intellectual property in the GenAI economy. The organization notes that patent data can help policymakers, businesses, and intellectual-property professionals identify where innovation is accelerating, which technologies are gaining traction, and how competitive dynamics are changing.

Patent information can serve several strategic functions.

For research and development teams, patent data can help identify areas of concentrated innovation and potential white space. For product teams, it can reveal technical approaches being pursued by competitors or adjacent industries. For legal departments, it can inform patentability, freedom-to-operate, licensing, acquisition, and defensive-publication decisions.

Patent data should not be treated as a perfect representation of the market. Companies differ in their reliance on patents, trade secrets, publication, and speed of execution. Patent applications also become public only after a delay. Nevertheless, the scale and direction of filing activity can provide an important indicator of where organizations are committing technical and financial resources.

WIPO’s central message is that decisions being made now about what to protect, where to file, and how to operate in an increasingly crowded field may influence competitive positions for years.

Practical Considerations for GenAI Innovators and Patent Owners

The accelerated filing environment supports several practical steps for businesses developing or implementing GenAI technologies.

1. Establish a Recurring GenAI Invention-Harvesting Process

A single annual invention-review meeting may be insufficient for a field changing as rapidly as GenAI.

Companies should consider recurring invention-harvesting sessions with personnel involved in model development, data engineering, software architecture, cybersecurity, product deployment, and industry-specific implementation. The review should focus on technical problems solved during development—not merely on whether the project uses AI.

Questions may include:

  • What technical limitation did the development team encounter?
  • Why were available models or platforms inadequate?
  • What changes were made to improve accuracy, latency, reliability, security, or resource utilization?
  • Was a new architecture, data structure, workflow, or control mechanism developed?
  • Could a competitor implement the same result using a different model or platform?
  • Which aspects should remain confidential, and which should be patented?

Because patent publication data lag behind filing activity, waiting until competitors’ portfolios become visible may leave a company reacting to strategies adopted many months earlier.

2. Focus Patent Applications on Technical Differentiation

A patent application should not rely solely on labels such as “generative AI,” “large language model,” or “machine learning.”

The application should explain the relevant technical architecture, inputs, processing steps, system interactions, and resulting improvements. Where applicable, it should describe how the claimed technology improves computer operation, data processing, network performance, model execution, security, industrial control, or another technical process. See, e.g., PatentNext: Artificial Intelligence (AI) Patenting Handbook: Version 3.0. 

The goal is to identify what the company actually invented—not merely the commercially attractive result produced by the system.

3. Draft Specifications That Can Accommodate Technological Change

Model terminology and preferred architectures can change rapidly. A specification drafted around only one currently popular model may become unnecessarily narrow as the technology develops.

Where supported by the invention, the specification should describe alternative model types, deployment arrangements, data sources, processing sequences, and implementation mechanisms. It should also distinguish between features that are essential to the invention and features that are merely examples.

This approach can provide flexibility during prosecution and reduce the risk that claims become obsolete when a particular model, platform, or architecture is replaced.

4. Use a Layered Claim Strategy

A GenAI patent application may benefit from claims directed to different levels of the technology.

Independent claims may address the core technical process or system architecture. Dependent claims may address narrower implementations, including particular model types, retrieval techniques, agent workflows, validation mechanisms, data structures, interfaces, security controls, or deployment environments.

Claims should also be considered across appropriate statutory forms, such as system, method, and computer-readable-medium claims. Depending on the invention, additional claims may address training, inference, deployment, monitoring, or interaction with physical systems.

A layered approach can provide both broader commercial coverage and narrower fallback positions during prosecution.

5. Coordinate Patent Protection With Trade-Secret Strategy

Not every GenAI innovation should necessarily be patented.

Certain training techniques, datasets, model parameters, evaluation procedures, or internal deployment practices may be difficult for competitors to observe and may therefore be candidates for trade-secret protection. Other innovations may be visible in a product, discoverable through testing, or likely to be independently developed, making patent protection more important. See, e.g., PatentNext: AI-based Inventions: Patenting vs. Trade Secret Considerations. 

The decision should be made deliberately. It should account for detectability, reverse engineering, employee mobility, publication risk, enforceability, and the expected commercial life of the technology.

6. Monitor Both Traditional and Nontraditional Competitors

As GenAI patenting expands across industries, competitive monitoring should extend beyond well-known AI and software companies.

A business may encounter relevant patents owned by customers, suppliers, infrastructure providers, universities, research institutions, or companies in adjacent industries. Patent monitoring should therefore be organized around relevant technologies and technical functions, not only around a fixed list of competitors.

Conclusion

WIPO’s latest data confirm that GenAI patenting has moved into a period of exceptional growth. More than 56,000 GenAI patent families were published during 2024 and 2025—more than during the entire preceding decade—and GenAI now represents an increasing share of all AI-related patent activity.

The growth also reflects a broader change in the market. GenAI innovation is moving from early experimentation toward large-scale commercial deployment, and patent ownership is expanding beyond traditional technology companies into finance, telecommunications, infrastructure, and other industries.

For businesses, the practical lesson is not simply to file more patents. It is to identify technical innovation earlier, draft applications with sufficient implementation detail, preserve flexibility for changing architectures, coordinate patent and trade-secret protection, and monitor a rapidly evolving competitive landscape.

In a field moving this quickly, patent strategy cannot be separated from product and business strategy. The organizations that develop disciplined processes for identifying and protecting GenAI innovation now may be better positioned as today’s experimental systems become tomorrow’s commercial infrastructure.

****

Subscribe to get updates to this post or to receive future posts from PatentNext. Start a discussion or reach out to the author, Ryan Phelan, at rphelan@marshallip.com or 312-474-6607. Connect with or follow Ryan on LinkedIn.

PatentNext Takeaway: In Applications in Internet Time, LLC v. Salesforce, Inc., the Federal Circuit provided a useful reminder for drafting AI-related patent claims: dependent claims can help preserve broader independent-claim scope where the dependent claims separately recite narrower AI or agent-based implementations.

Although Applications in Internet Time was not a generative AI case, its reasoning is directly relevant to modern AI patent practice. The disputed claim language concerned “automatically detecting” changes, while a dependent claim separately recited “one or more intelligent agents” that performed that detection. The Federal Circuit held that claim differentiation provided a strong reason not to read the “intelligent agents” limitation into the broader independent claim.

For AI patent practitioners, the lesson is practical. When drafting or amending claims directed to AI systems, machine-learning workflows, autonomous agents, model-based processing, or AI-assisted automation, dependent claims should not be treated merely as fallback positions. They can also help preserve the distinction between a broad AI-enabled function and a narrower implementation of that function.

That strategy has limits. As cases such as Cave Consulting Group, LLC v. OptumInsight, Inc. show, later-added dependent claims cannot overcome a specification that consistently and affirmatively limits the invention to a narrower implementation. Thus, dependent claims can support claim differentiation only where the specification already supports the broader claim scope. 

Thus, the best practice is to draft both the specification and the claim set to support a deliberate hierarchy: broader AI functionality in the independent claims, and narrower model-, agent-, data-, or architecture-specific implementations in dependent claims.

****

Background: AI Claims Often Turn on the Level of Implementation Detail (Using Dependent Claims as More Than Fallback Positions)

AI patent claims frequently raise a familiar drafting problem: how much implementation detail should be included in the independent claim?

On one hand, claims that merely recite a desired AI result—such as “classifying data,” “generating a recommendation,” “detecting an anomaly,” or “automatically determining an output”—may face scrutiny under § 101, § 103, or § 112. Examiners may ask whether the claim recites a technological improvement, whether the claimed functionality is conventional, or whether the specification sufficiently describes how the AI functionality is actually performed.

On the other hand, overloading the independent claim with too much implementation detail can unnecessarily narrow the claim. For example, an independent claim that requires a particular type of model, a particular neural-network architecture, a particular training technique, or a particular agent-based workflow may be easier to distinguish during prosecution, but may also be easier for competitors to design around.

This is where dependent claims can play an important role.

A well-drafted AI claim set can separate the broader AI-enabled functionality from specific implementations. The independent claim may recite the broader technical operation, while dependent claims recite narrower embodiments such as:

  • a neural network;
  • a transformer-based model;
  • a large language model;
  • a reinforcement-learning policy;
  • a retrieval-augmented generation workflow;
  • one or more autonomous software agents;
  • a feature-extraction pipeline;
  • a vector database;
  • a prompt template;
  • a model-training workflow;
  • a post-processing rule set; or
  • a safety, validation, or guardrail process.

That structure can provide fallback positions. But it can also do something more: it can help show that the independent claim is not limited to the narrower implementation recited in the dependent claim.

The Prosecution Problem: Amendments Can Narrow Claims More Than Intended; but Claim-Differentiation can help redefine Scope

Software and AI-related patent applications often face multiple forms of scrutiny during examination. An examiner may reject the claims under § 101 as allegedly directed to an abstract idea. The examiner may also raise novelty or obviousness rejections under §§ 102 or 103, particularly where the claim recites broad software functionality. And, increasingly, examiners may raise § 112 issues where the claims recite technical functionality without enough supporting detail in the specification. See PatentNext: USPTO Examiners issue more Written Description (Section 112) rejections following Precedential Ex Parte Desjardins decision.

In response, applicants often amend independent claims to provide more technical specificity. That may be necessary and appropriate. For example, an applicant may amend a claim to recite a particular data structure, computer architecture, model-training workflow, communication sequence, or control process.

But such amendments raise a recurring strategic issue: how can the applicant distinguish the prior art or clarify the invention without unintentionally limiting the independent claim to a single implementation?

One answer is to use dependent claims deliberately. When an applicant amends an independent claim, the applicant should consider whether additional dependent claims should be added to capture narrower implementations. These dependent claims may later help demonstrate that the independent claim remains broader than those specific implementations.

For example, consider the following simplified claim set:

  1. “A computer-implemented method comprising automatically detecting a change in application data and updating a user interface based on the detected change.”
  2. “The method of claim 1, wherein automatically detecting the change comprises using one or more intelligent agents.”

In that example, claim 2 can help support the argument that claim 1 is not limited to intelligent agents. Claim 2 adds that specific implementation. Therefore, reading claim 1 to already require intelligent agents would risk making the dependent claim redundant.

That is the basic claim-differentiation point. 

The doctrine of claim differentiation generally recognizes that different claims are presumed to have different scope. The doctrine is particularly powerful where a dependent claim adds a limitation that an accused infringer later seeks to import into the independent claim.

In practical terms, if independent claim 1 recites “automatically detecting an anomaly,” and dependent claim 2 recites that the detecting is performed “using a trained neural network,” there is a claim-differentiation argument that claim 1 should not be limited to neural-network-based detection.

Likewise, if independent claim 1 recites “generating a response based on input data,” and dependent claim 2 recites that the response is generated “using a transformer-based large language model,” there is an argument that claim 1 should not be construed to require a transformer-based LLM.

Of course, claim differentiation is not absolute. The specification and prosecution history still matter. But when the intrinsic record supports broader scope, dependent claims can become important claim-construction evidence.

That is the lesson illustrated by Applications in Internet Time. 

Applications in Internet Time v. Salesforce: A Recent AI / Software Example

In Applications in Internet Time, LLC v. Salesforce, Inc., the Federal Circuit addressed AI-based software patents directed to dynamically generated applications. Nos. 2024-1133, 2024-1685, 2024 WL 4487251 (Fed. Cir. Oct. 10, 2024) (nonprecedential). The claims involved computer systems including intelligent agents, server computers, client computers, browser applications, application layers, and a “change management layer” for automatically detecting changes that affect an application.

The district court construed “automatically detecting” to require “detecting without human intervention through the use of one or more intelligent agents.” That construction became case-dispositive. Because the accused Salesforce products allegedly did not use intelligent agents in the manner required by the district court’s construction, the district court granted summary judgment of non-infringement.

The Federal Circuit reversed that claim-construction ruling.

The key claim-differentiation issue was straightforward. Independent claim 1 recited a “change management layer for automatically detecting changes that affect an application.” But dependent claim 8 expressly recited that the change management layer comprised “one or more intelligent agents.” The Federal Circuit found that this claim structure provided a strong reason not to import the “intelligent agents” limitation into the independent claim.

That aspect of the decision is useful for software patent practitioners because it shows how a dependent claim can preserve broader independent-claim scope. The independent claim recited the broader software functionality: automatically detecting changes. The dependent claim recited a narrower way to perform that functionality: using intelligent agents. Because the narrower implementation appeared in the dependent claim, the Federal Circuit declined to read that implementation into the independent claim.

The court also rejected the argument that the specification limited the invention to intelligent agents. Although the specification discussed intelligent agents, the Federal Circuit viewed those disclosures as exemplary rather than limiting. The court explained that the repeated use of intelligent agents in the best-mode discussion showed that intelligent agents may be a preferred implementation, not that they were required by the claims.

That distinction is important. In software patents, specifications often describe one implementation in detail. But unless the specification or prosecution history clearly limits the invention to that implementation, the claims should not automatically be confined to it. Dependent claims can reinforce that point by expressly claiming the narrower implementation separately.

That distinction is critical for AI patent practice. 

Why AIT Matters for Software and AI Claim Drafting

The AIT decision is nonprecedential. Even so, it provides a useful and recent illustration of a practical drafting point: dependent claims can help separate broad AI and software functionality from specific implementation details.

That distinction is especially important for modern software and AI inventions. Consider the following examples:

  • an independent claim recites “classifying input data,” while a dependent claim recites that the classification uses a neural network;
  • an independent claim recites “generating a response using a machine-learning model,” while a dependent claim recites that the model is a transformer-based large language model;
  • an independent claim recites “retrieving context data,” while a dependent claim recites retrieval from a vector database;
  • an independent claim recites “automatically detecting an anomaly,” while a dependent claim recites detection using a trained anomaly-detection model;
  • an independent claim recites “modifying an interface based on user activity,” while a dependent claim recites a specific event-listener or agent-based implementation.

In each example, the dependent claim may help preserve the broader scope of the independent claim. If the specification supports multiple ways to perform the claimed function, dependent claims can make that breadth visible in the claim set.

This can be especially valuable after an amendment. For example, if an applicant amends an independent claim to overcome prior art by reciting “automatically detecting a change in a deployed application,” the applicant may also add dependent claims reciting specific detection mechanisms. Those dependent claims can serve as both fallback positions and claim-differentiation anchors.

The claim set then communicates a hierarchy:

  • the independent claim covers the broader technical concept;
  • dependent claim 2 covers implementation A;
  • dependent claim 3 covers implementation B;
  • dependent claim 4 covers implementation C.

That hierarchy may later help rebut an accused infringer’s attempt to limit the independent claim to only one disclosed implementation.

Modern AI applications may involve software agents, autonomous agents, LLM agents, planning agents, monitoring agents, retrieval agents, classification agents, or model-based decision agents. In some applications, the agent is the invention. In others, the agent is one possible implementation of a broader automated process. 

Cave Consulting: The Important Cautionary Example

The usefulness of dependent claims has limits. The Federal Circuit’s decision in Cave Consulting Group, LLC v. OptumInsight, Inc. illustrates the other side of the doctrine. 725 F. App’x 988 (Fed. Cir. 2018). 

In Cave Consulting, the claims related to computer-implemented methods for analyzing physician efficiency using medical claims data. The dispute concerned whether the claimed “weighted episode of care statistics” covered direct standardization or was limited to indirect standardization.

The patentee relied on dependent claims that specifically recited direct standardization. The argument was that, under claim differentiation, the independent claims should be broad enough to cover direct standardization because the dependent claims expressly recited it.

The Federal Circuit disagreed. The problem was the specification. The court concluded that the specification repeatedly and consistently described the invention as using indirect standardization and distinguished that approach from direct standardization used in the prior art. In that context, the later-added dependent claims could not overcome the limiting description in the specification.

That is the key caution: claim differentiation is a tool of claim construction, not a substitute for written-description support. Dependent claims can help preserve broad claim scope only if the specification supports that breadth.

This point is particularly important when dependent claims are added during prosecution. If the original specification describes only one implementation as the invention, and disparages or excludes alternatives, later-added dependent claims may not be enough to broaden the independent claim. Worse, such dependent claims may invite written-description challenges if the specification does not reasonably convey possession of the later-claimed alternative.

Thus, the drafting lesson is twofold:

  1. Use dependent claims to preserve meaningful claim-scope distinctions.
  2. Draft the specification from the outset to support those distinctions.

Practice Tips for Patent Prosecutors

The practical takeaway is that dependent claims should be drafted with future claim construction in mind. When amending AI and software claims, practitioners should consider the following strategies.

1. Add dependent claims that expressly recite narrower implementations

If the independent claim recites broader functionality, consider dependent claims that recite specific implementations. For example:

  • “wherein the detecting is performed using one or more intelligent agents”;
  • “wherein the classifying is performed using a trained neural network”;
  • “wherein the retrieving comprises querying a vector database”;
  • “wherein the generating comprises applying a transformer-based language model”;
  • “wherein the updating comprises transmitting a synchronization message using a publish-subscribe protocol.”

These dependent claims may provide fallback positions and help show that the independent claim is not limited to those narrower implementations.

2. Avoid prosecution remarks that collapse the claim hierarchy

Dependent claims are less useful if the applicant’s remarks describe the independent claim as requiring the narrower dependent-claim feature. For example, if claim 1 recites “automatically detecting” and claim 2 recites “using intelligent agents,” the applicant should be careful before arguing that “the claimed invention requires intelligent agents” unless that is truly intended.

A better approach may be to distinguish the independent claim based on its actual amended language, while preserving dependent claims as additional, narrower implementations.

3. Draft the specification to support multiple implementations

Claim differentiation works best when the specification supports the broader genus. For software and AI inventions, the specification should identify alternative implementations where possible.

For example, if an invention involves automatic detection, the specification might describe detection using rules, event listeners, intelligent agents, machine-learning models, polling, message queues, or other mechanisms. If an invention involves classification, the specification might describe neural networks, decision trees, support vector machines, rules-based classifiers, or other models.

The goal is not to list alternatives without substance. The goal is to provide enough technical detail to show possession of the broader concept and its representative implementations.

4. Be careful with “the invention” language

Courts may treat repeated descriptions of “the invention” as limiting in some circumstances, particularly where the specification consistently characterizes the invention as requiring a particular feature. Patent drafters should therefore use care when describing embodiments.

Rather than stating that “the invention uses an intelligent agent,” it may be preferable to state that “in some embodiments, the system uses an intelligent agent,” or that “the automatic detection may be performed using one or more intelligent agents, event listeners, polling routines, rules-based engines, machine-learning models, or other detection mechanisms.”

That type of drafting can preserve flexibility and support later claim-differentiation arguments.

5. Use dependent claims to create a deliberate claim hierarchy

A strong software claim set often has a layered structure:

  • an independent claim directed to the broader architecture or technical process;
  • dependent claims directed to particular implementation mechanisms;
  • dependent claims directed to data structures, model types, communication protocols, user-interface behavior, or deployment environments;
  • dependent claims directed to performance improvements or technical effects.

This hierarchy can be valuable during prosecution, during continuation practice, and later during claim construction.

Conclusion: Dependent Claims as Claim-Construction Assets

Dependent claims should not be treated as an afterthought. In AI, software, and computing patents, they can be especially valuable because software inventions are often implemented in multiple ways. A claim set that captures those implementation differences can preserve flexibility during prosecution and provide important claim-construction support later.

Applications in Internet Time v. Salesforce illustrates the upside. A dependent claim reciting “intelligent agents” helped prevent that limitation from being imported into broader independent claims directed to automatic detection.

Cave Consulting illustrates the caution. Dependent claims cannot expand claim scope beyond what the specification supports, particularly where the specification consistently limits the invention to a narrower implementation.

The best practice is therefore clear: when amending software claims, practitioners should not only ask what language will overcome the rejection. They should also ask what dependent claims are needed to preserve the intended claim hierarchy.

In other words, dependent claims are not merely backup claims. Properly drafted, they can be claim-construction assets.

****

Subscribe to get updates to this post or to receive future posts from PatentNext. Start a discussion or reach out to the author, Ryan Phelan, at rphelan@marshallip.com or 312-474-6607. Connect with or follow Ryan on LinkedIn.
PatentNext Takeaway: On April 30, 2026, the USPTO issued a memorandum titled “Best Practices for Submission of Rule 132 Subject Matter Eligibility Declarations (SMEDs),” updating the Office’s December 4, 2025 guidance to applicants and practitioners.  The new memorandum reinforces the Office’s SMED framework and characterizes it as a living body of guidance informed by practitioner experience.

The result is not a change in law or procedure, but a signal: the USPTO views SMEDs as an increasingly important evidentiary tool for resolving § 101 issues in emerging and fact‑intensive technologies, particularly artificial intelligence and diagnostics.

Continue Reading USPTO Updates SMED Best Practices

PatentNext Takeway: Ex parte Desjardins—and especially the USPTO’s decision to make it precedential—appears to be shifting examination away from § 101 and toward § 112 written-description scrutiny, particularly for AI-related inventions. For AI-related inventions, a central takeaway is that practitioners should expect more examiner demands for concrete disclosure of how an AI model is trained, what inputs and outputs are used, how preprocessing and post-processing occur, and how inference or agentic workflows actually operate. Prosecution data and a recent office action example also suggest that written-description rejections are increasing both overall and in AI applications. The practical implication is that patent applicants should not rely on high-level “black box” AI descriptions, but instead should draft specifications with enough technical detail to demonstrate possession of the claimed invention.

Continue Reading USPTO Examiners issue more Written Description (Section 112) rejections following Precedential Ex Parte Desjardins decision

PatentNext Summary: The USPTO has rescinded its February 2024 inventorship guidance for AI-assisted inventions and replaced it with revised guidance issued on November 28, 2025, so prior materials relying on the earlier guidance should be treated as outdated. The revised guidance emphasizes traditional conception-based inventorship, makes clear that AI may assist but cannot be an inventor, and flags a practical priority risk where a foreign filing naming an AI system as the sole inventor can undermine U.S. priority claims. It also underscores that the guidance reflects USPTO examination policy—not binding law—so courts (or Congress) may ultimately provide the controlling rules.

Continue Reading The USPTO’s Revised Guidance regarding AI-Assisted Inventions

PatentNext Summary: An Information Disclosure Statement (IDS) is the primary procedural vehicle for satisfying the duty of candor and good faith owed to the USPTO during patent prosecution. The consequences of failing to disclose material information can be severe, including a later finding of inequitable conduct and resulting unenforceability of an issued patent. This article summarizes the legal framework governing materiality, the scope of the disclosure duty, foreign and parallel-application considerations, and practical IDS best practices for attorneys seeking to reduce risk while building a strong prosecution record.

Continue Reading The Pitfalls of Failure to Disclose Material Information to the USPTO and Information Disclosure Statement (IDS) Best Practices

Following the USPTO’s high-profile actions in Desjardins, the next question was how that guidance would play out in ordinary PTAB appeals. Ex parte Carmody provides an early answer.

The decision itself is short. The analysis is sparse. And that is precisely why it matters.

Continue Reading Ex parte Carmody: A Quiet but Important Signal on AI Eligibility Under §101

On December 4, 2025, the United States Patent and Trademark Office (USPTO) issued two memoranda addressing the use of Subject Matter Eligibility Declarations (“SMEDs”) during patent prosecution, both from Director John Squires.  The first, the SMED Examiner Memo, targets the Patent Examining Corps, clarifying how examiners should treat applicant-submitted evidence under 37 CFR 1.132 in traversing subject matter eligibility (SME) rejections.  The second, the Best Practices for SMEDs Memo, addresses the legal community, emphasizing strategies for maximizing the value and probative weight of SMEDs.  This article summarizes both memos, offering practical insights for innovators, patent professionals, and stakeholders navigating the Section 101 landscape.

Continue Reading USPTO Issues Guidance on Subject Matter Eligibility Declarations (“SMED”)

In our earlier posts, we discussed the significance of Ex Parte Desjardins: first when the Appeals Review Panel vacated the § 101 rejection, and again when Director Squires designated the decision as precedential.

Today, the USPTO has taken the next step: it has formally issued a memo to the examining corps announcing updates to the MPEP that incorporate Desjardins directly into the Office’s subject-matter eligibility framework.

Continue Reading Further Update: USPTO Issues Memo Integrating Desjardins Into the MPEP

PatentNext Summary: Announcing the IPO’s AI Patenting Handbook V3.0, which is a newly updated third edition of IPO’s practical guide for attorneys working with AI-related inventions and technologies. It offers a clear framework for understanding modern AI (including foundation models and generative AI), drafting and prosecuting stronger AI patent applications, and navigating enforcement, global practice, and emerging AI inventorship and governance issues—designed as a day-to-day reference for in-house and outside counsel.

Continue Reading Artificial Intelligence (AI) Patenting Handbook: Version 3.0